LAUNCH BUNDLE · EARLY ACCESS

Professional, consistent images without additional software, in any image generator.

Julieta is a deterministic framework for generating images with artificial intelligence in a precise, repeatable and professional way. It does not use Seeds, ControlNet, IP-Adapter, LoRAs, etc.

Manual + early framework + prompts + 25 cards + Discord · USD 150USD 75 50% OFF

Full bundle until December 11, 2026. After that, the same price includes the manual and Discord; prompts and cards are sold separately.

-- days-- hours-- min

Creative Commons framework. The Julieta framework is free under the CC BY-SA 4.0 license. The explanatory manual, the prompts, the style cards and the accessories are protected by all rights reserved © copyright.

Manual cover

Is it possible to keep consistency in visual generation with “artificial intelligence”?

When generating images with AI, the system can produce different results even when you ask for the same thing. You generate a subject, ask for it to appear in another scene, and the machine changes the face, the age or the ethnicity. To work professionally you need to repeat a scene, change a single variable, or keep a subject’s identity across many images.

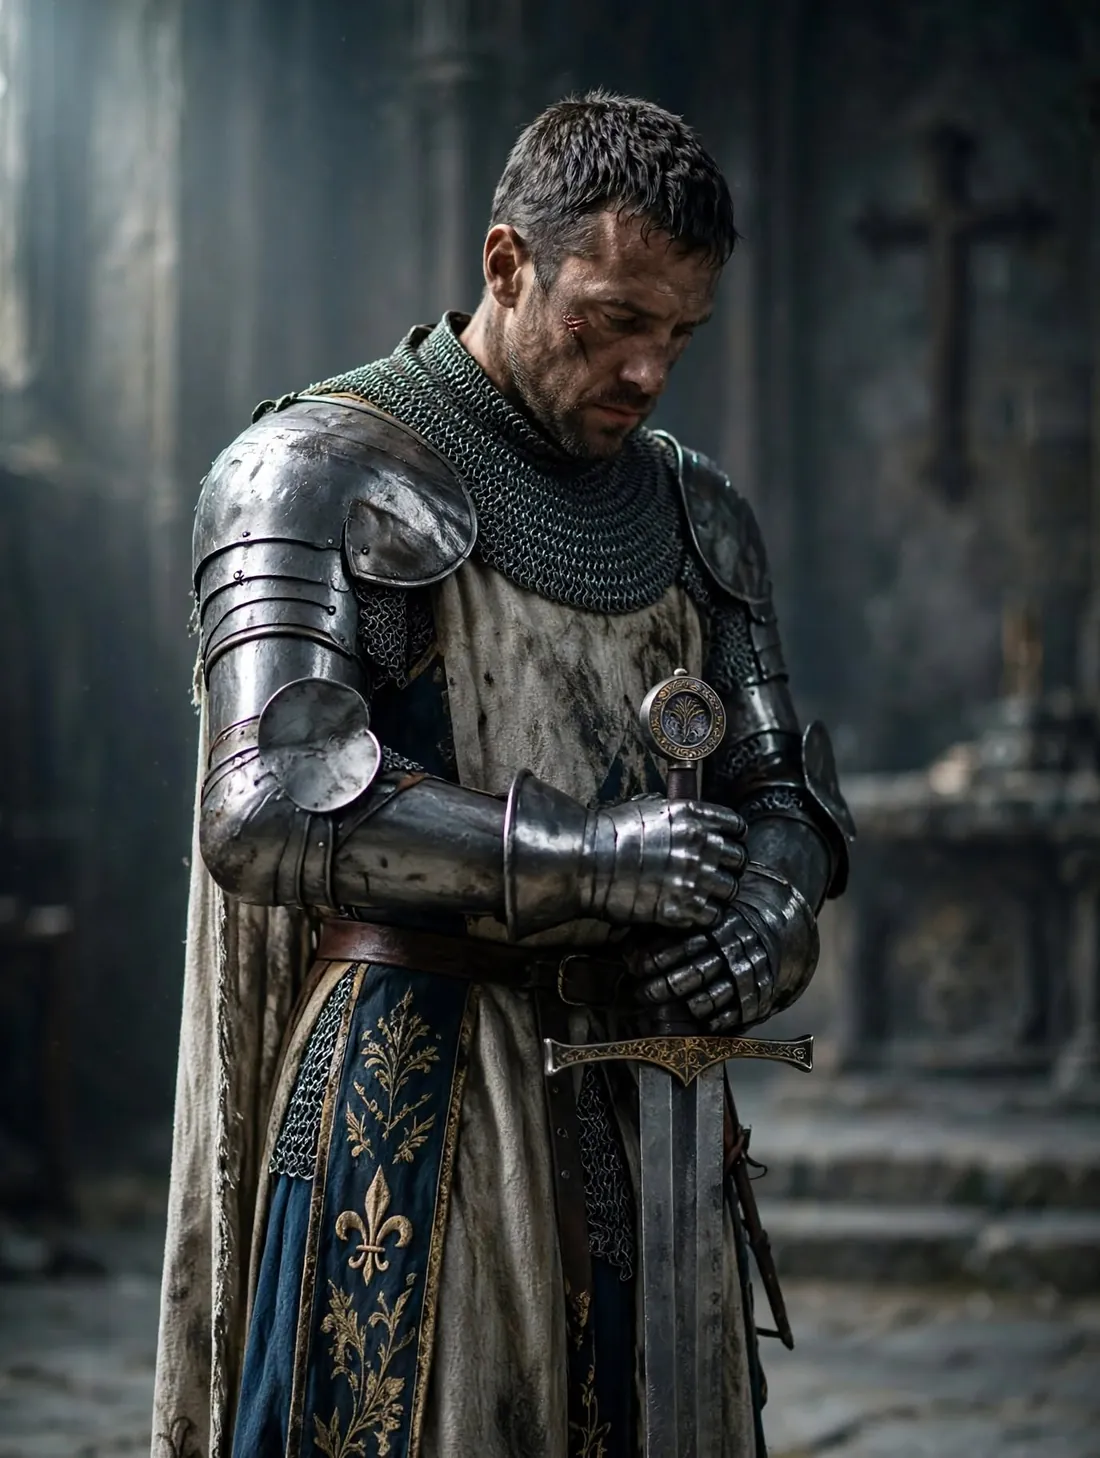
Armored knight with his face visible, leaning on his sword in a dim temple
Face visible
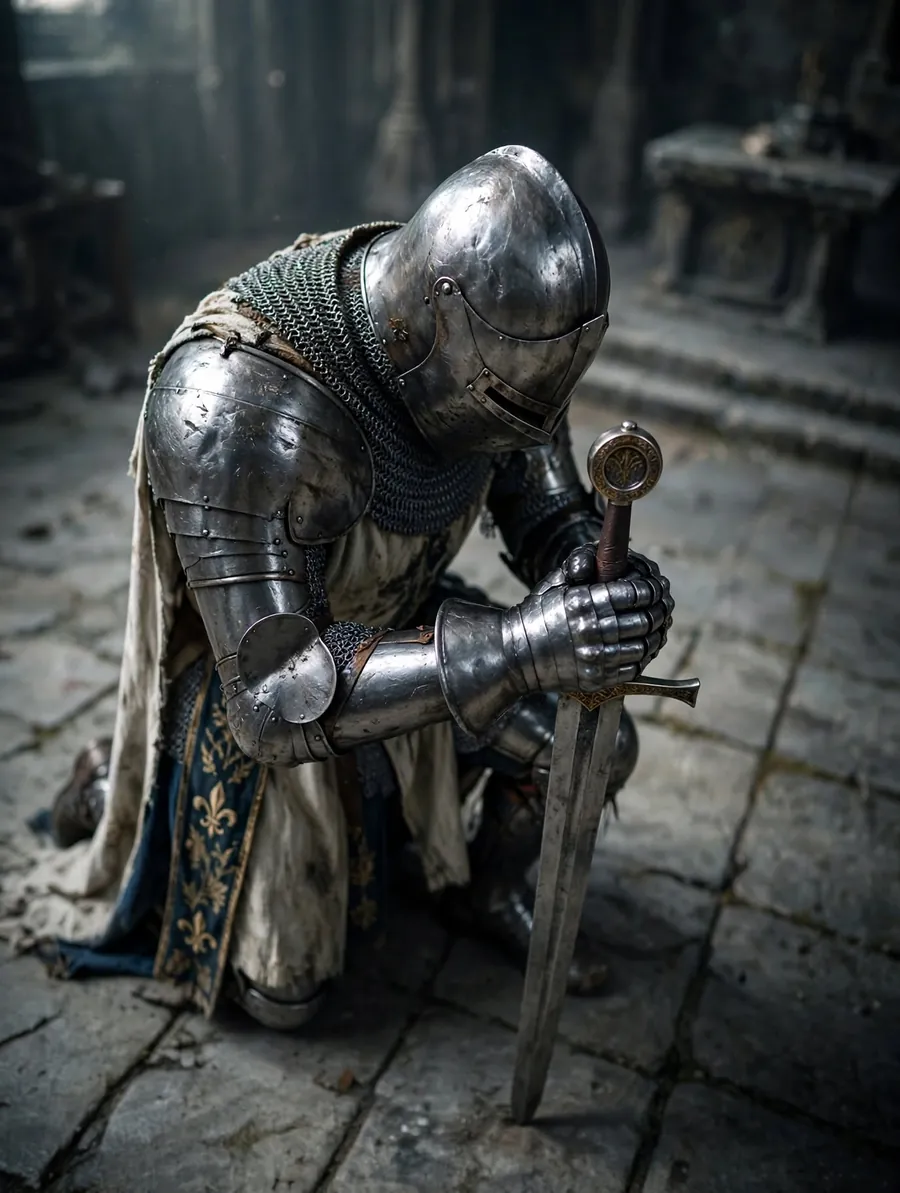
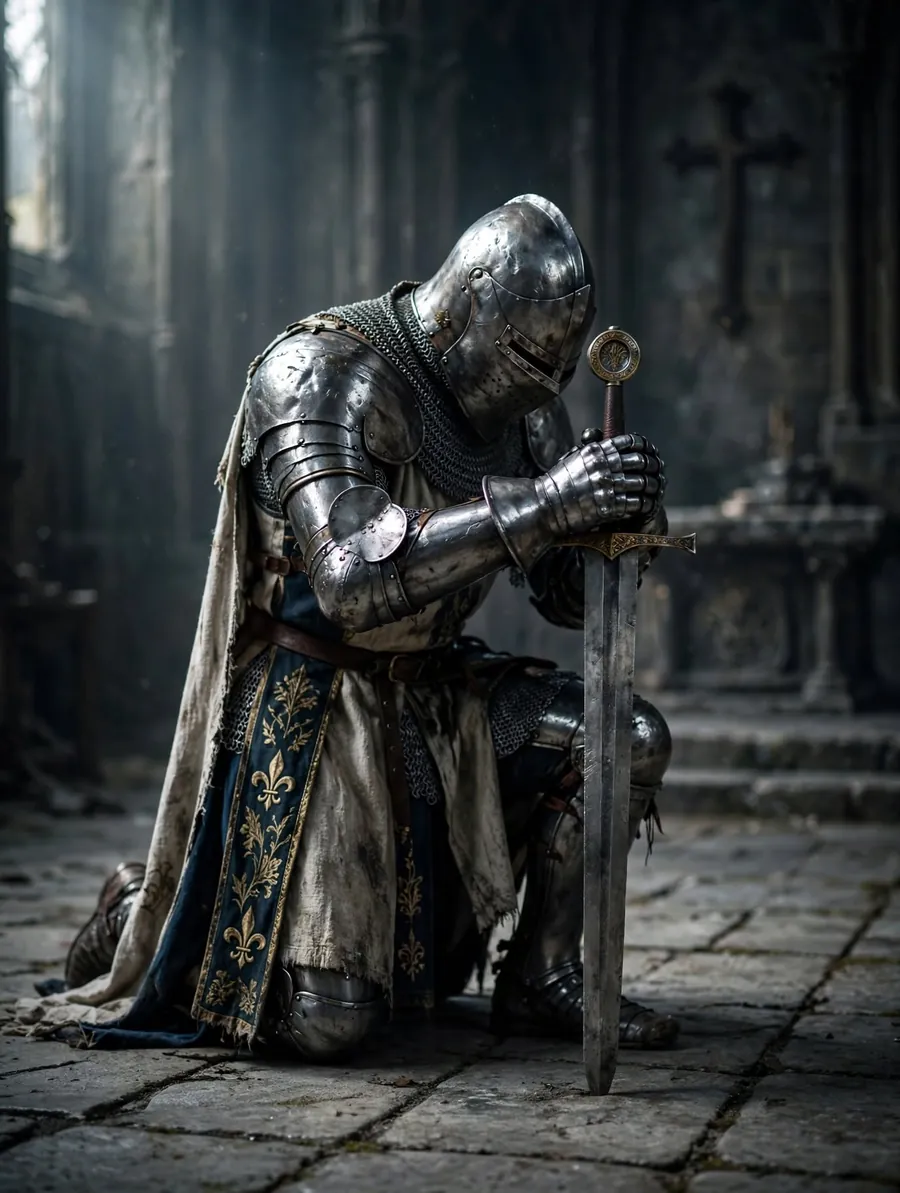
Helmeted knight kneeling on one knee, sword planted in front of him
Helmet, kneeling
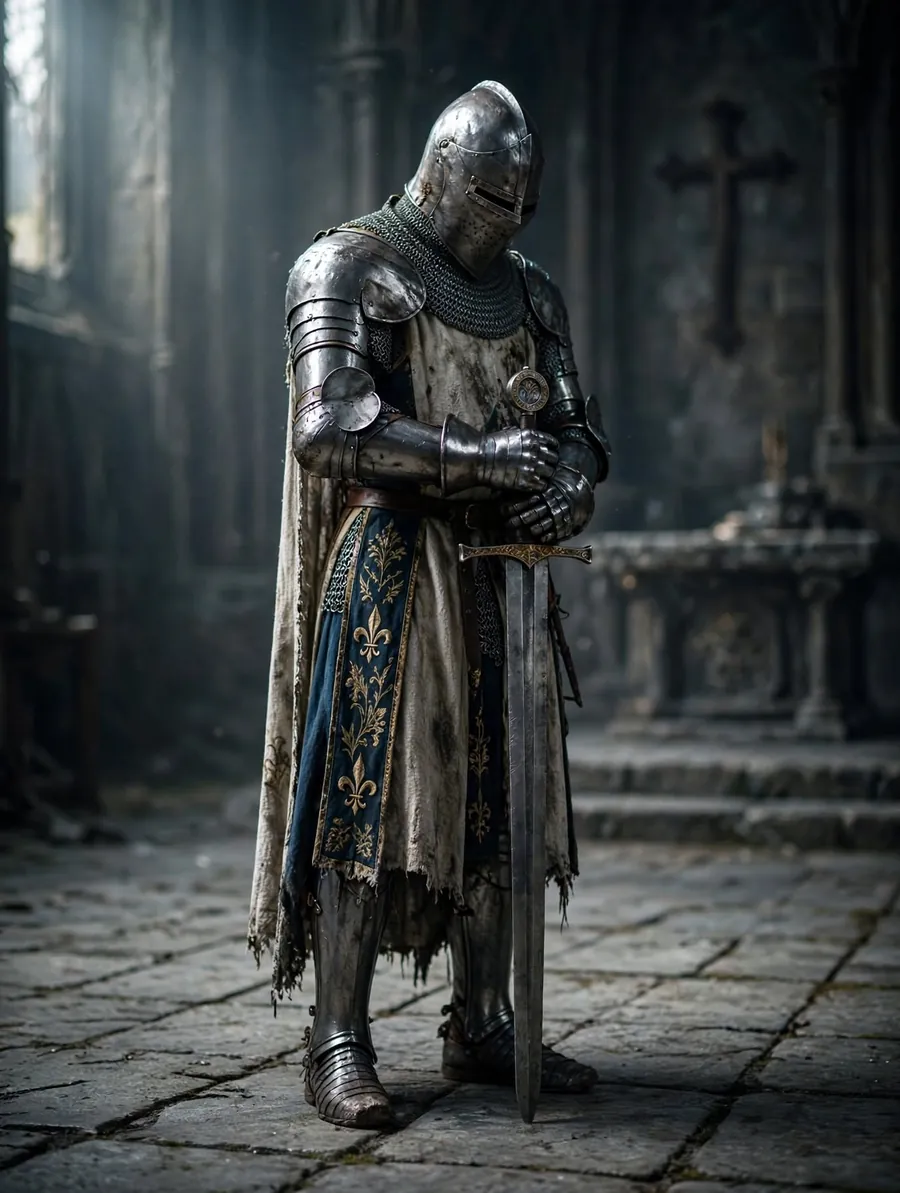
Helmeted knight standing, hands resting on the sword hilt
Standing
Helmeted knight bowed in prayer, forehead resting on the sword
Another framing
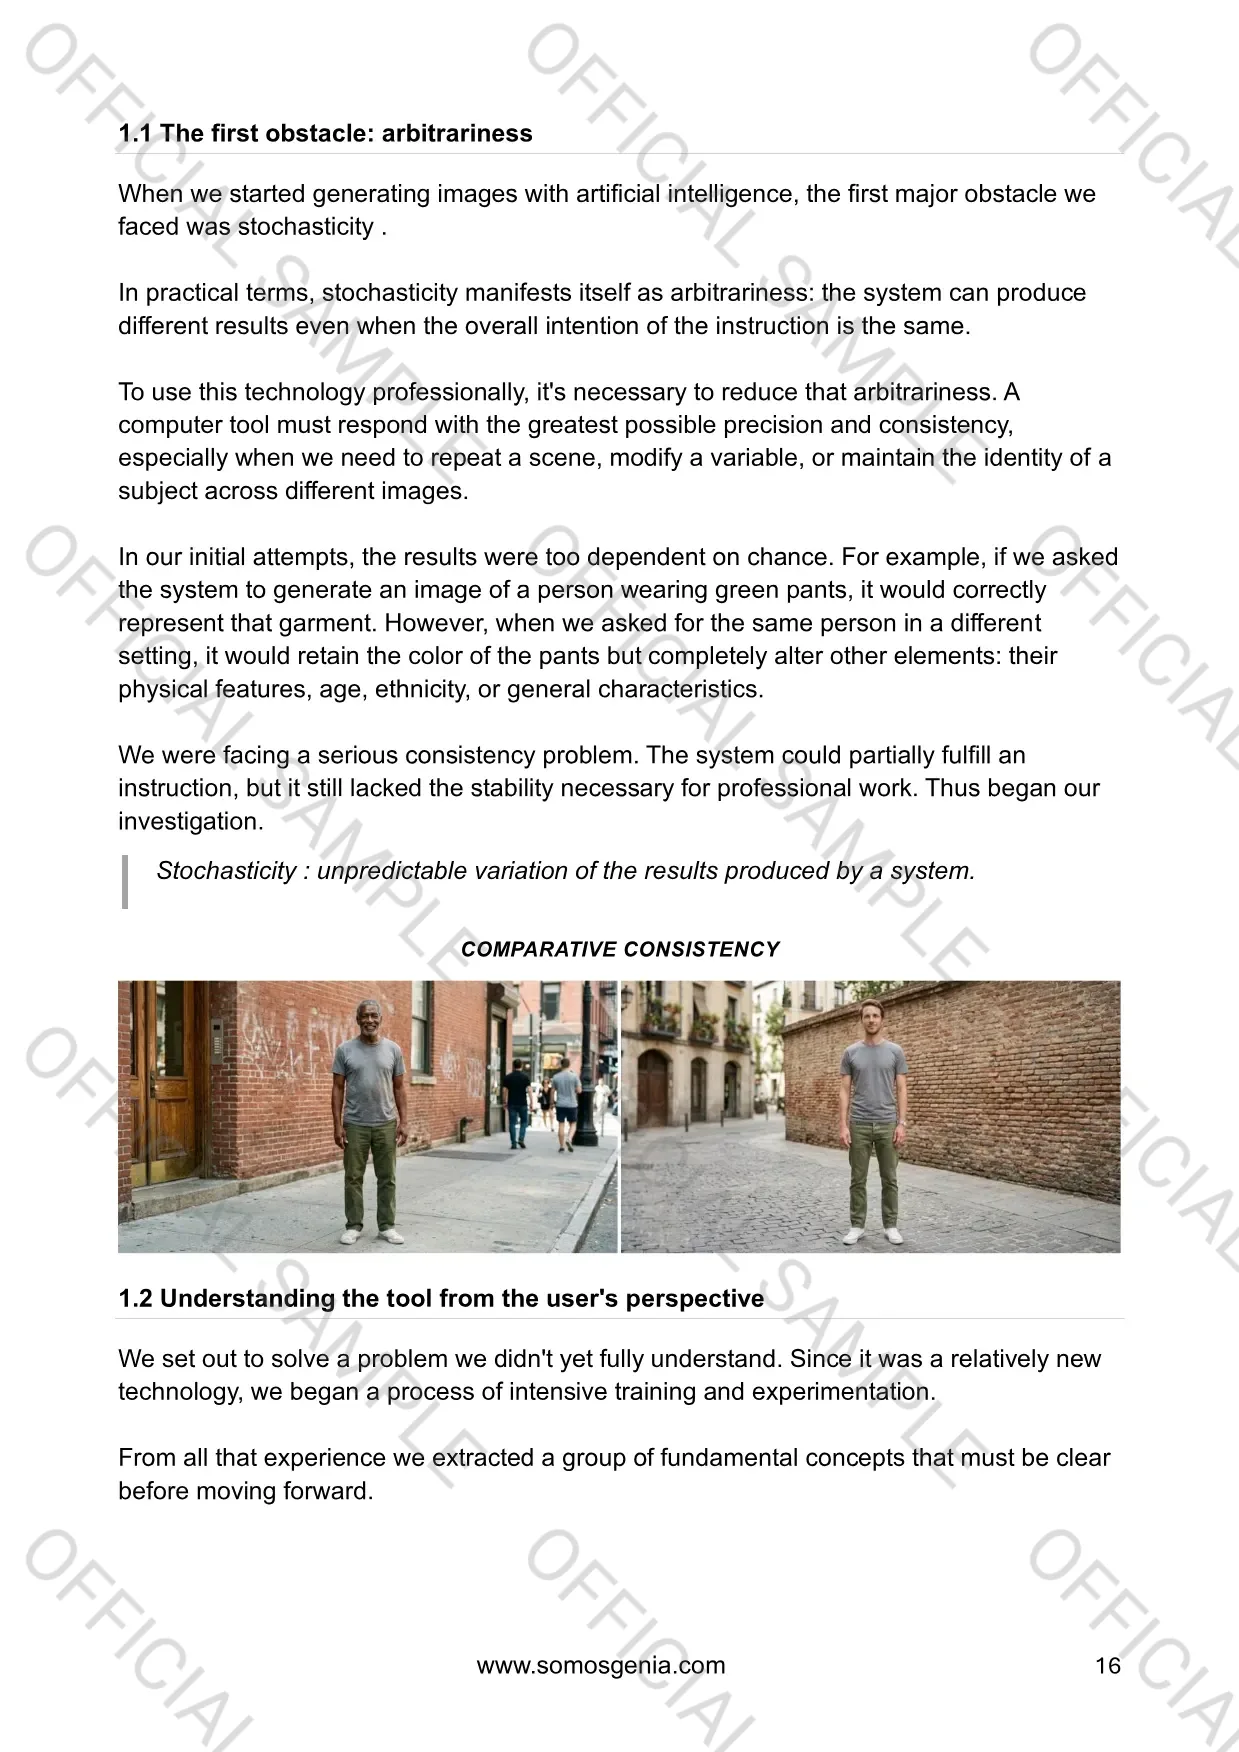
Manual page 16: The first obstacle, arbitrariness, with the comparative consistency images

The beginning of the manual.

The manual starts from the problem: why generative AI changes what was not requested. Here, the first obstacle: arbitrariness.

Official sample with watermark. Select the image to enlarge it.

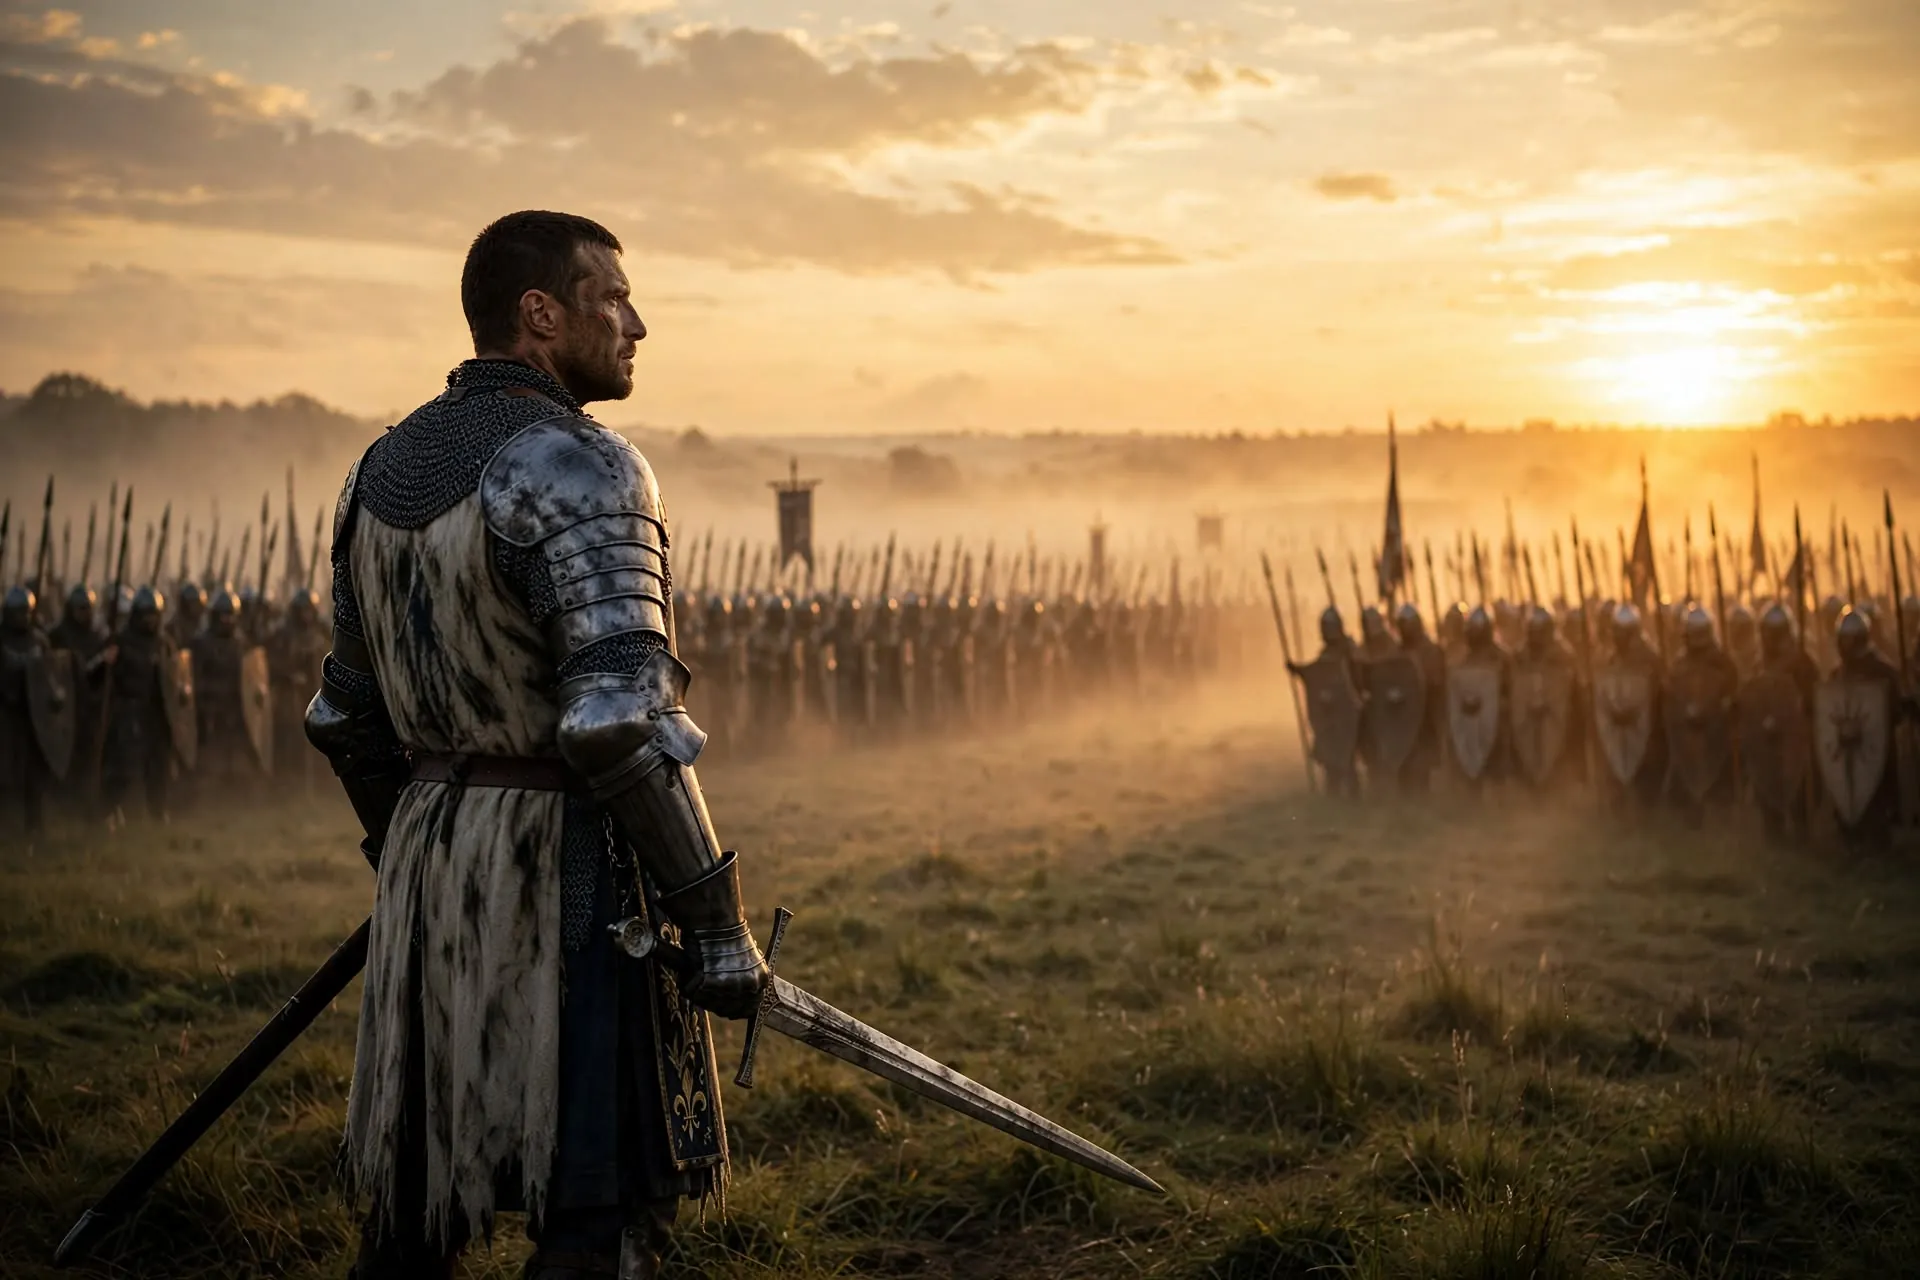
Knight seen from behind at sunrise, facing an army drawn up in a misty field

The goal is to use the machine only to render the image, keeping it away from artistic decisions.

Verifiable results.

Many results, one scene.

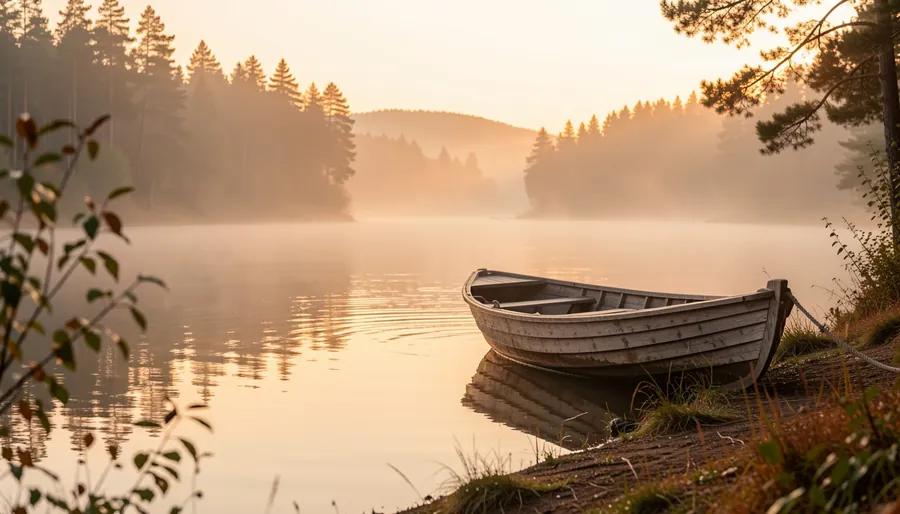
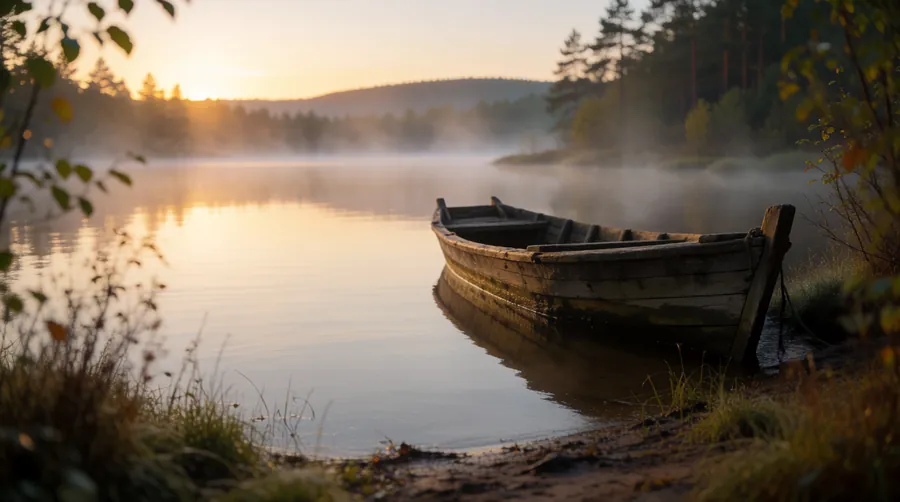
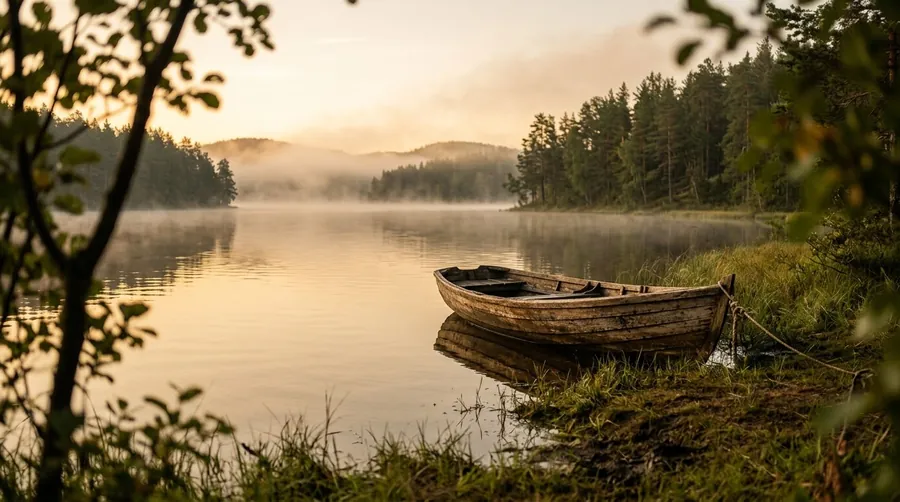
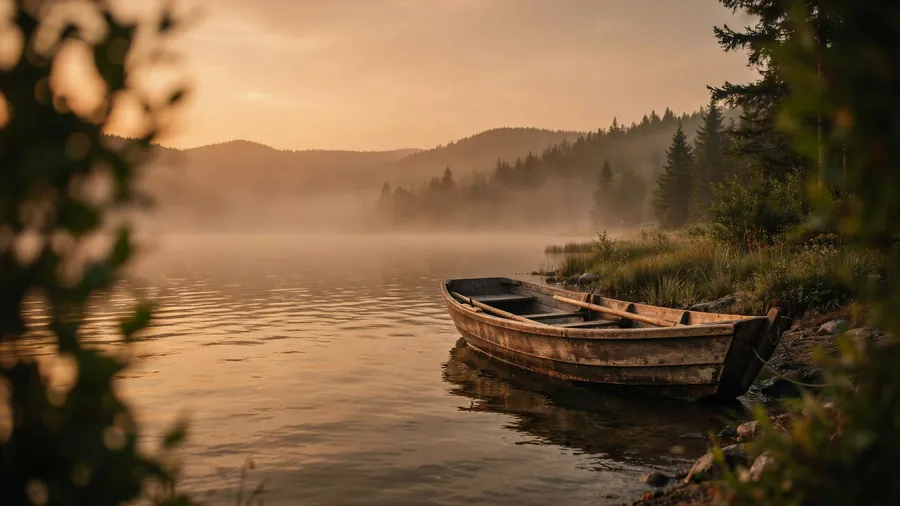
One composition, generated on different models. The visual style changes with the model, while the structure of the scene is kept semantically.

Lake scene generated with Flux 2 Klein 9B Fast
Flux 2 Klein 9B Fast
Lake scene generated with Krea 2 medium
Krea 2 medium
Lake scene generated with Nano Banana 2
Nano Banana 2
Lake scene generated with Ideogram 4.0
Ideogram 4.0

Julieta uses the language machines were trained in: variables, tags and visual conditions. Instead of a loose sentence, you define the world of the image: the subjects, the space, the materials, the light, the camera and the composition. Because it is organized into modules, you can change the lighting without touching the subject, or the environment without losing the composition.

Deterministic, in the strict sense of the word: given the same conditions, the result is determined. In Julieta, results are exact semantically: every element of the scene is defined and not left to the model’s interpretation.

Creative Commons framework: the Julieta framework is published under the Creative Commons Attribution-ShareAlike 4.0 license (CC BY-SA 4.0). Anyone can use, adapt and share it, including commercially, by crediting Somos Genia and sharing adaptations under the same license. It is published on GitHub on November 27, 2026. The explanatory manual, the prompts, the style cards and the accessories are protected by all rights reserved © copyright.

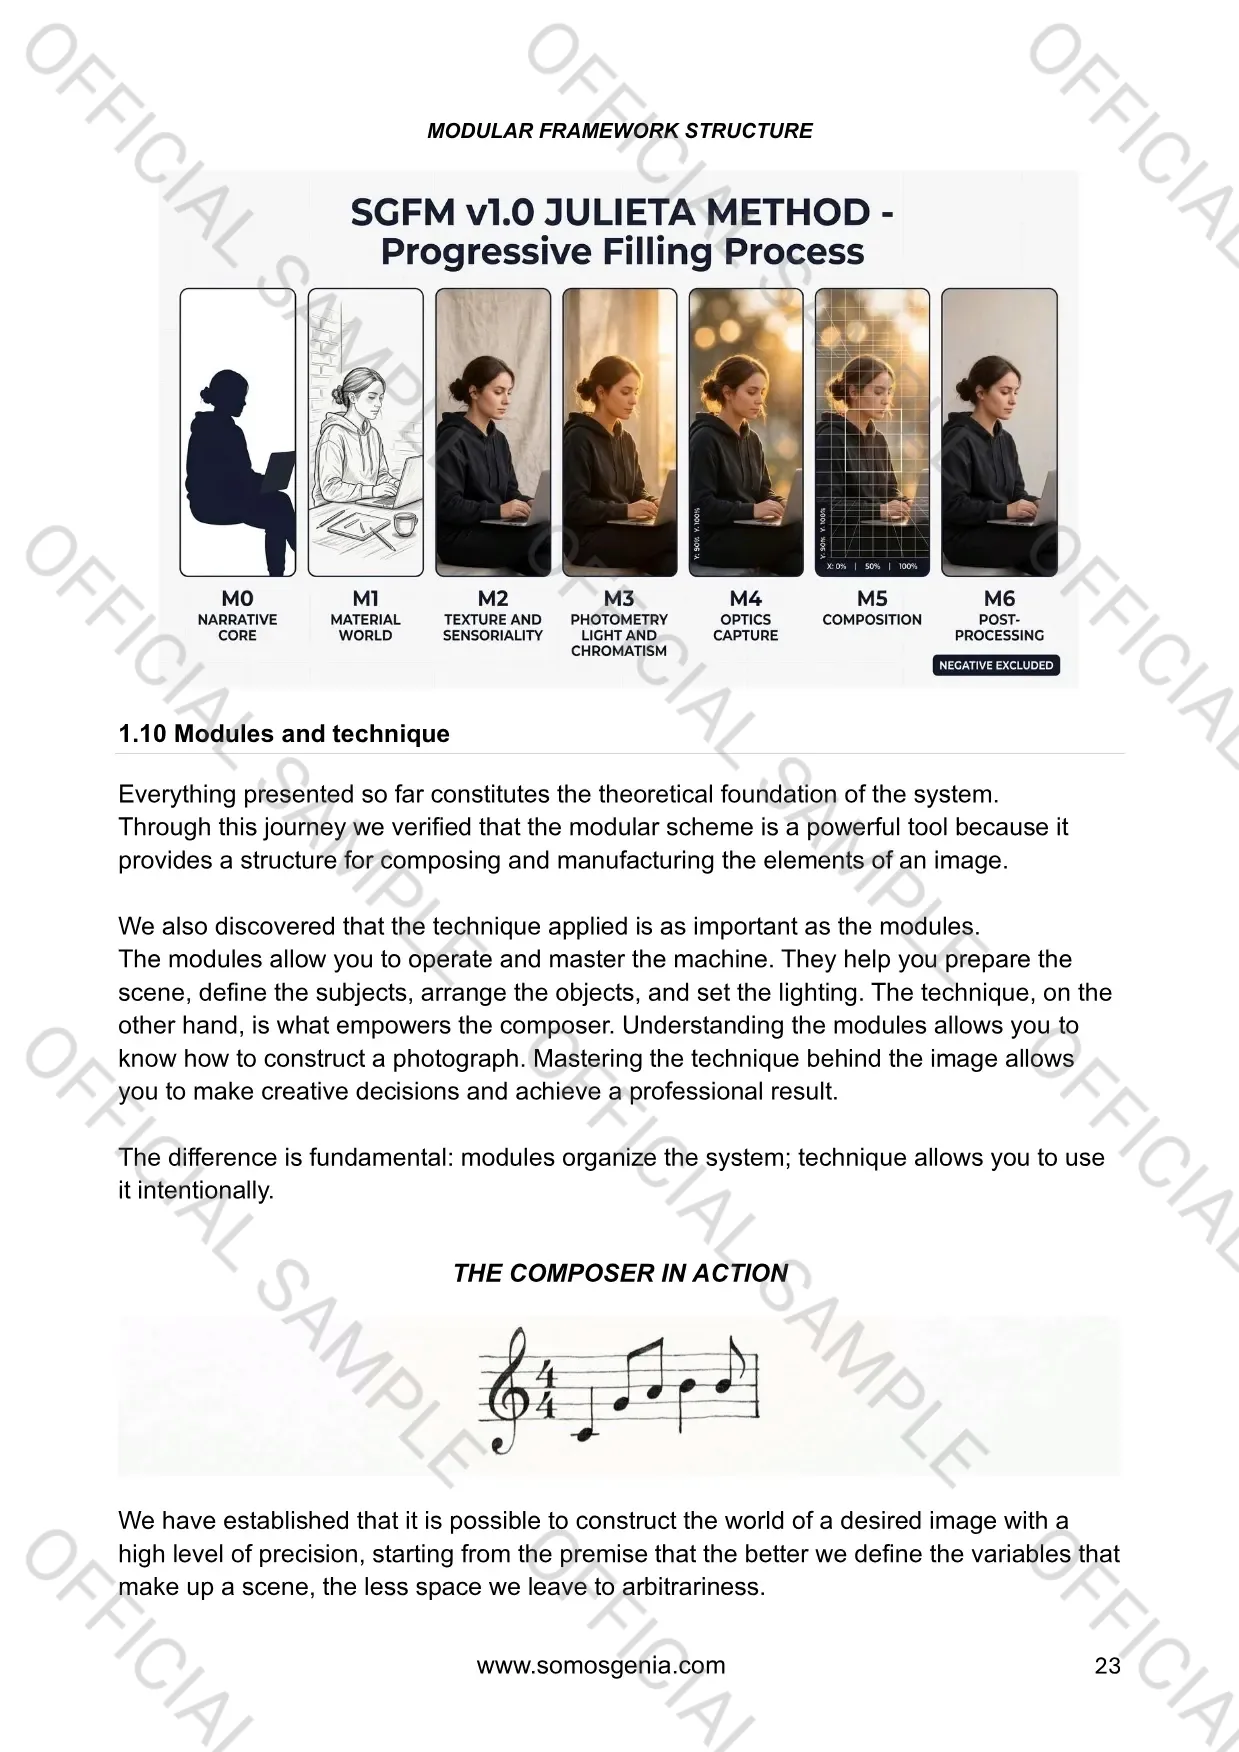
Manual page 23: modular framework structure, from M0 to M6, showing the progressive filling process

The seven modules, in one diagram.

The progressive filling process: from the narrative core to post-processing, the image is built module by module.

Official sample with watermark. Select the image to enlarge it.

Contents of the launch bundle.

01

The Julieta manual

Seven chapters to master the framework: why AI is probabilistic, the seven modules (M0 to M6) plus the negative module, the properties, prompt extraction, iteration with LLMs and style samples. For any profile, with or without technical experience.
02

Discord access

A community to share results, ask questions and learn alongside the Somos Genia team. Always included with the manual.

03

Early framework (CC BY-SA 4.0)

The Julieta framework files, under the Creative Commons BY-SA 4.0 license: free to use, adapt and share with attribution. It is published on GitHub on November 27, 2026; bundle buyers get it earlier.

04

Advanced prompts

The prompts from the most advanced part of the manual, ready to use.

05

25 style cards

Each card is a ready-to-use style: it brings the values for modules 2, 3 and 6, its negative prompt and an example image. Cards for use in one’s own creations, simply and quickly.

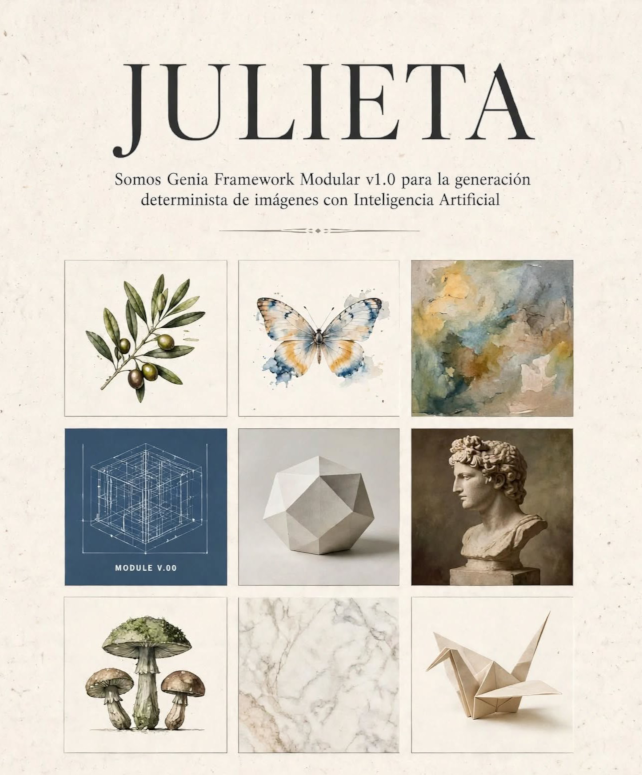
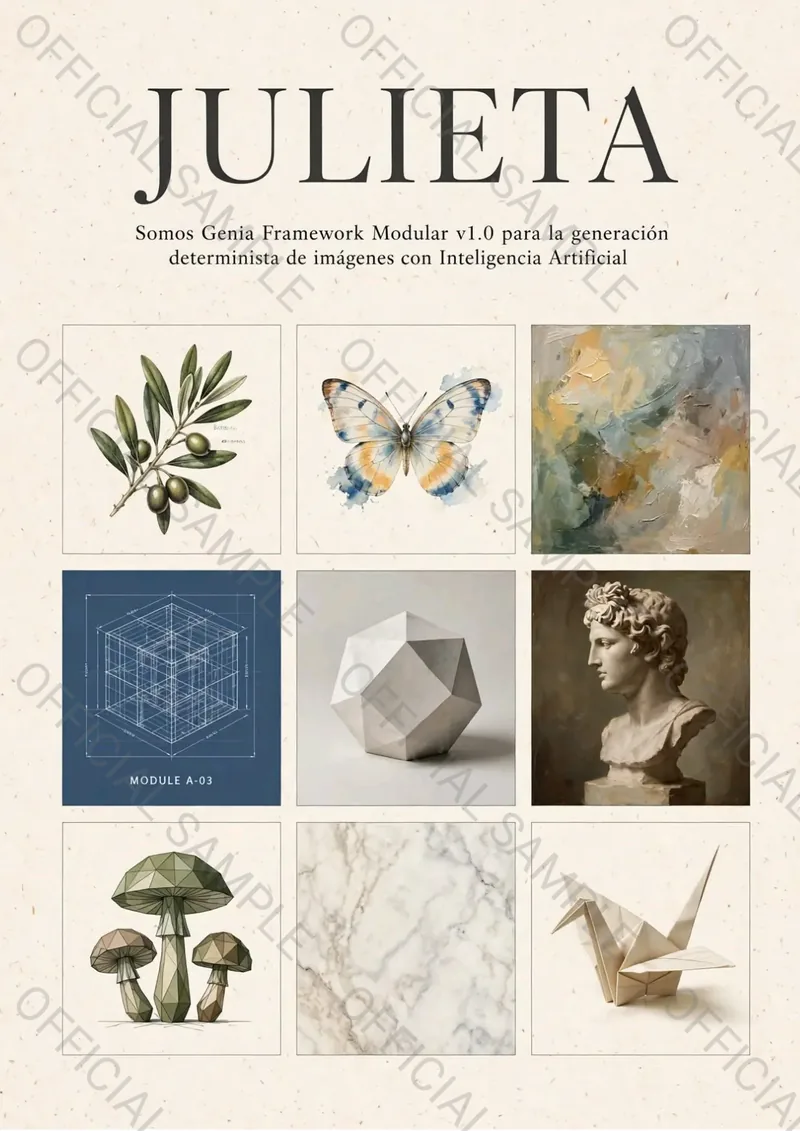
Julieta manual cover, with a grid of nine images

Presentation of the manual.

Somos Genia Modular Framework v1.0 – Julieta, for deterministic image generation with artificial intelligence.

Official sample with watermark.

All of this for USD 75 (50% off, was USD 150) until December 11, 2026.

Works with any diffusion model: Flux, Krea, Nano Banana, GPT Image, Ideogram, Recraft and more.

25 ready-to-use styles.

A card is selected, its values are adjusted and the image is generated. These are a few of the 25 cards. They are included in the bundle until December 11, 2026.

  1. 1 Selection of a card
  2. 2 Adjustment of the values
  3. 3 Generation of the image
Style card Industrial automotive render, with the values for modules 2, 3 and 6 and a gray sports car in a concrete garage
Style card Vector flat design
Style card Stylized family 3D animation, with an animated fox among flowers
Style card Stylized 3D render, with a white robotic character with neon lights
Style card Urban documentary photography, with a cobbled street with a bakery and a bookshop
Style card Atmospheric fog photography, with a foggy forest

Who is it for?

It is intended for those who:

  • Generate images with AI and require greater control and less trial and error.
  • Work as designers, content creators, photographers or in advertising.
  • Need to keep a character or a scene consistent.
  • Wish to learn a universal method.

It is not intended for those who:

  • Seek non-professional solutions.
  • Expect pixel-identical images across different models: exactness derives from the semantic structure, while style derives from the model.
  • Require a software tool: Julieta is a method.

A moment of light.

We are a team from Buenos Aires, Argentina, researching image generation with AI. Julieta was born from practice: we tested, trained our own models, and found that the problem was not the technology but how we communicated with it. This manual is the path we walked, told so that you can use it from day one.

Somos Genia Team

USD 150USD 75 50% OFF

Manual + early framework (CC BY-SA 4.0) + advanced prompts + 25 style cards + Discord

Buy now

Full bundle until December 11, 2026. After that, USD 150 includes the manual and Discord; prompts and cards are sold separately.

Framework license: Creative Commons CC BY-SA 4.0. The explanatory manual, the prompts, the style cards and the accessories are protected by all rights reserved © copyright

Before you buy.

Because it is digital content delivered immediately, refunds are not offered. For inquiries prior to purchase, write to hola@somosgenia.com.

Frequently asked questions

What exactly is being purchased?

The manual that explains the framework step by step and Discord access. Until December 11, 2026, the bundle also adds the early framework, the advanced prompts and the 25 style cards. The framework itself is Creative Commons (CC BY-SA 4.0).

May the framework be used freely?

Yes. The framework is under the Creative Commons CC BY-SA 4.0 license: it may be used, adapted and shared, including commercially, by crediting Somos Genia and keeping the same license. The CC BY-SA 4.0 license applies exclusively to the framework. All accessory content (manual, prompts and style cards) is protected by all rights reserved (copyright).

Is previous experience required?

No. The manual is designed for any profile.

What software is required?

Any diffusion-based image generator. Julieta does not depend on any one in particular.

What language are the prompts in?

The prompts are delivered in the language of the version purchased: Spanish in the Spanish version and English in the English version.

How is the content received?

Automatically, from Gumroad: the manual and the Discord invitation are received and, while the bundle lasts, the early framework, the advanced prompts and the 25 style cards.

How is Discord accessed?

The invitation is received together with the purchase.

What happens when the bundle ends?

After the deadline the price goes from USD 75 to USD 150 and includes the manual and Discord. Prompts, cards and everything new are sold separately. The framework remains free (CC BY-SA 4.0).

Are the results exact?

Yes, semantically: Julieta determines what the image contains and how it is composed. What changes between models is the rendering style, not the scene. Pixel-identical images are not promised.

Is support available?

Yes, by email at hola@somosgenia.com and on Discord.

Build your next image.

Acquire the launch bundle